Honeyguide
Self-updating catalogue site for 95 Apify scrapers
- Pages generated
- 102
- Hand-maintained content
- 0 pages
- Data refresh
- Hourly
- Build hardening
- 2 slots, 10 retries
- Content engine tests
- 33
- Publish step
- Pull request
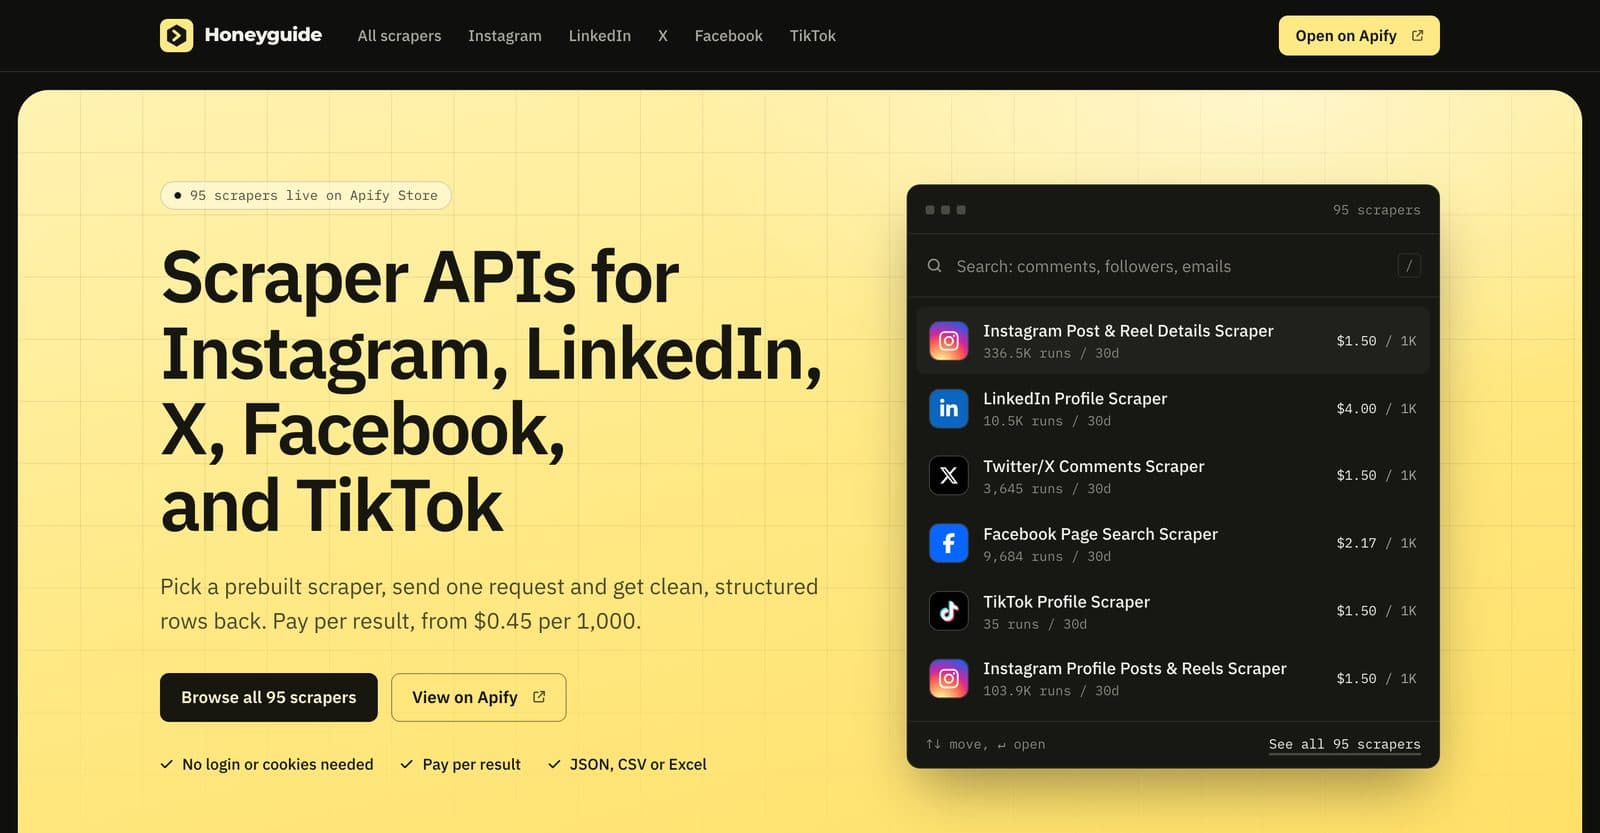
Honeyguide is the public catalogue for the Data Slayer scrapers. Every public scraper gets its own page with specs, inputs, output fields, code samples, pricing and FAQ, all generated from Apify's public API and refreshed hourly. A companion content engine drafts blog posts from the same data, runs them through quality gates and opens a pull request on the site repo.
The problem
The scrapers existed only as Apify Store listings, which are hard to search, group by platform, or find through a search engine. Maintaining a separate site by hand for close to a hundred actors would drift out of date within weeks as prices, inputs and usage numbers change. The site had to be zero-maintenance: anything published on Apify appears automatically, anything private never can.
How it is built
A Next.js App Router site reads two public Apify endpoints: the store listing for names, pricing and usage, and each actor's default build for its input schema and output fields. Responses are cached for an hour, so pages stay current with no API token and no manual edits. A scraper's platform is inferred from the first word of its Apify name.
Cold builds request every scraper at once, so the data layer runs through a small concurrency gate (two requests in flight) with up to ten jittered retries. That change stopped builds failing on Apify's per-second rate limit.
The site, each platform hub and each scraper page gets its own generated social card, structured data, sitemap entry and FAQ. Hand-written MDX files in src/content can layer a guide or extra FAQs onto any page without replacing the generated parts.
The content engine is a Python pipeline. It syncs fact sheets from the same Apify API, writes a post with an LLM agent, generates images, then runs deterministic gates: SEO and AI-citation scores, a fact check against the sheets, internal link checks and a compile of the MDX with the site's own compiler. A post can only state facts present in the sheets, and publishing means opening a pull request; merging it makes the post live.
What it taught me
- Reading from the same public source the product itself uses removes a whole class of stale-content bugs; the site cannot disagree with the Store.
- Rate limits bite hardest at build time when everything is requested at once; a tiny concurrency gate with jittered retries fixed more than any cache did.
- An LLM pipeline is safe to automate only when deterministic gates own the final say: compile the output with the real compiler and block on any unverified fact.
Architecture
Visitors and search engines hit a Next.js site whose pages are rendered from Apify's public API and cached for an hour, with optional hand-written MDX layered on top. Separately, a Python worker pulls fact sheets from the same API, drives an LLM agent through write, enrich, verify and revise stages, records jobs in Postgres, and opens a pull request on the site repository. Merging the PR publishes the post.
Layer 1
VisitorClient
Browsers and search engines
→ Next.js site (requests page)
Content engineWorker
Stages and quality gates
→ Apify public API (fact sheets) → LLM agent (staged prompts) → Postgres (jobs and links) → GitHub PR (opens PR)
Layer 2
Next.js siteEdge
Generated pages, hourly cache
→ Apify public API (store and build data) → MDX content (reads MDX)
LLM agentModel
Write, verify, revise
PostgresStore
Jobs, history, link registry
GitHub PRService
Review, then merge to publish
→ MDX content (merge publishes)
Layer 3
Apify public APIExternal
Store listing and builds
MDX contentStore
Guides and posts in the repo
Stack
Frontend
- Next.js 16 (App Router)
- React 19
- Tailwind CSS 4
- MDX
Backend
- Python 3 pipeline
- Streamlit dashboard
- Node MDX compile check
Data
- Apify public Store and build endpoints
- PostgreSQL job queue and link registry
Infrastructure
- Serverless hosting with incremental revalidation
- Docker Compose (dashboard and worker)
- GitHub pull requests as the release gate
AI
- Claude Agent SDK for write, enrich, verify and revise stages
- Generated hero and inline images